DeepSeek open-sources DeepInfer, the engine that runs its AI service
On 20 October 2026, DeepSeek published DeepInfer on GitHub under the Apache 2.0 licence. DeepSeek describes it as the inference framework that powers its large-scale production services. This first release supports DeepSeek-V4.1-Flash, runs on NVIDIA SM100 GPUs and Huawei Ascend 950 chips, and leaves out parts needed for a complete service.
The short version
- 01DeepSeek released DeepInfer, its inference framework, on GitHub on 20 October 2026.
- 02It is Apache 2.0 licensed and starts with DeepSeek-V4.1-Flash.
- 03It supports NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs.
- 04The release does not include a KV cache system, full prefill and decode splitting, or load balancing.
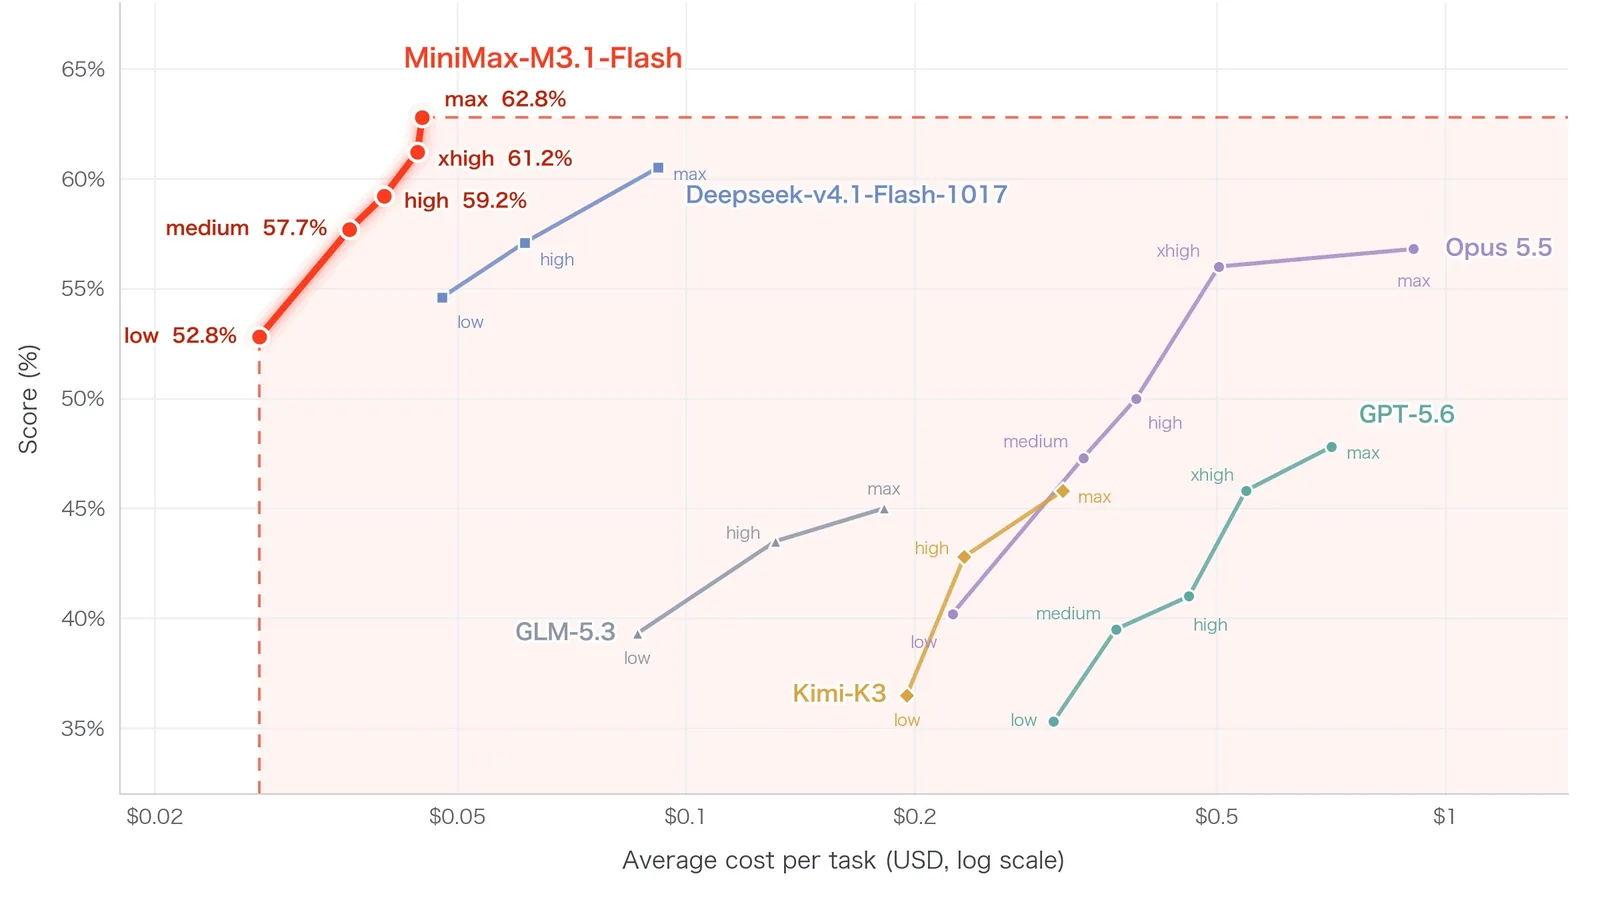
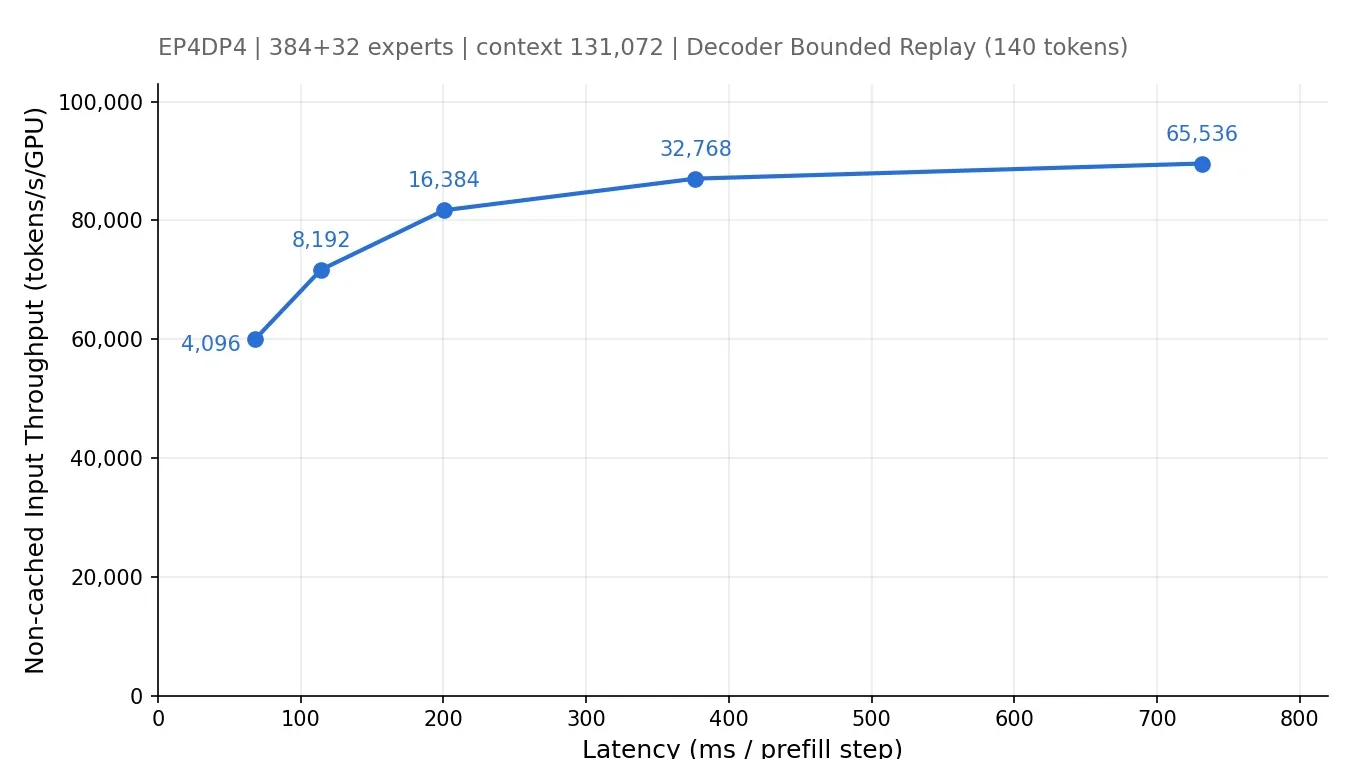
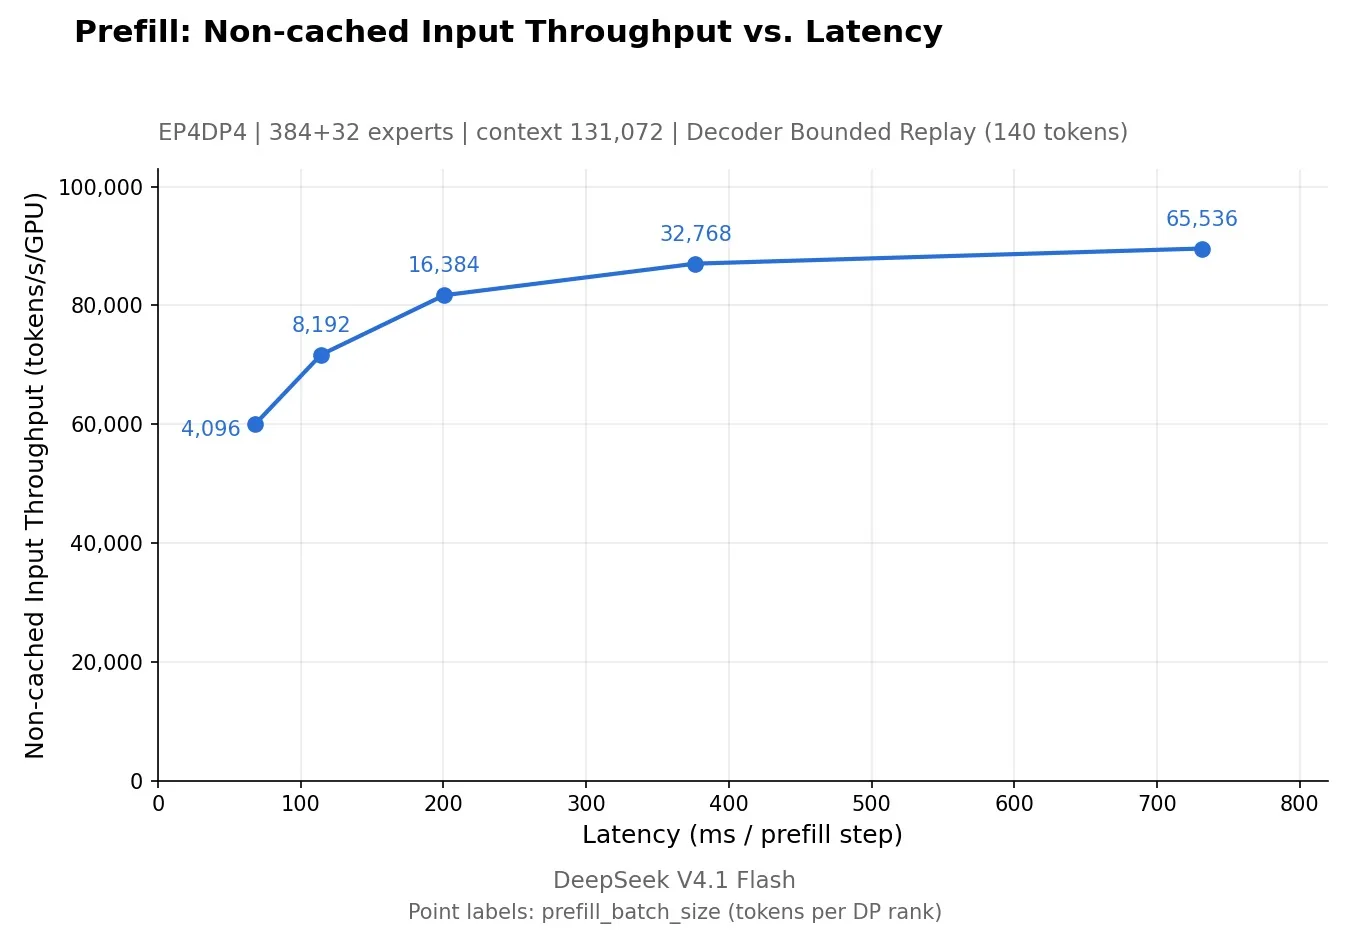
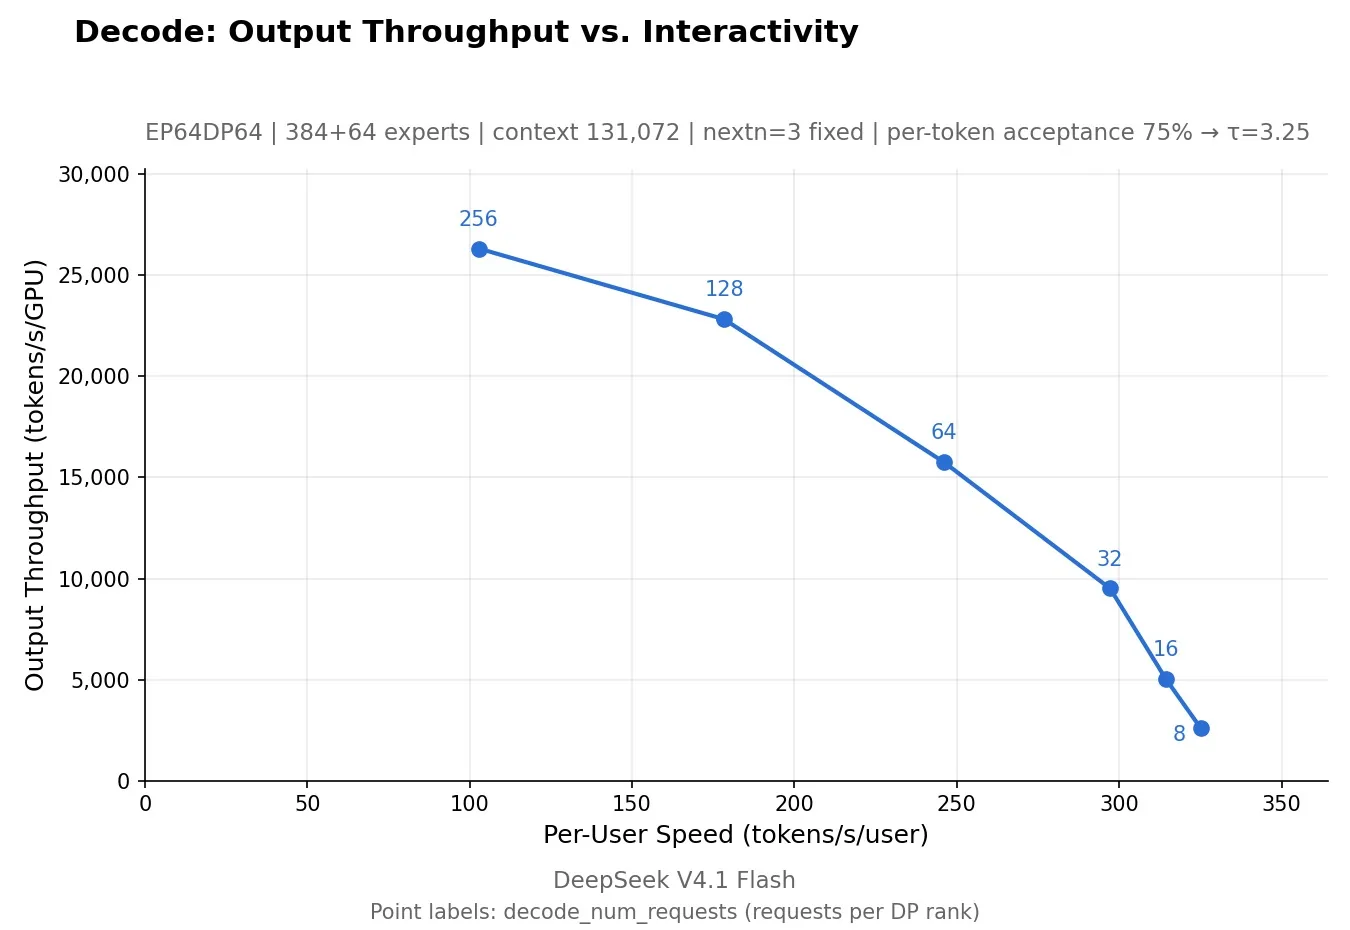
- 05The benchmark charts are DeepSeek's own measurements.
At a glance
| Released | 20 October 2026 |
|---|---|
| Company | DeepSeek |
| Name | DeepInfer |
| Licence | Apache 2.0 |
| First supported model | DeepSeek-V4.1-Flash |
| Hardware | NVIDIA SM100 GPUs, Huawei Ascend 950 NPUs |
| Where | github.com/deepseek-ai/DeepInfer |
| Status | Confirmed |
What is DeepInfer?
DeepInfer is, in DeepSeek's words, "the high-performance inference framework that powers DeepSeek's large-scale production services." Inference means running a trained AI model to answer requests.
The code went up on GitHub on 20 October 2026. DeepSeek says this open-source release provides offline inference with the core features needed for serving at scale.
What can it do?
The listed features include optimised kernels, several ways of splitting work across GPUs, faster decoding with draft tokens, asynchronous scheduling, deterministic sampling and structured outputs that follow a JSON schema.
It supports one model for now, DeepSeek-V4.1-Flash, and runs on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs.
What is not included?
DeepSeek lists three things a complete service needs that are not in this release: a KV cache system, prefill and decode disaggregation (it says most of the required engine functionality is already implemented), and load balancing across data-parallel replicas.
What licence does it use?
DeepInfer is released under the Apache License 2.0, which lets people use and change the code, including in commercial work, with conditions set out in the licence.
Why does it matter?
Most AI labs keep the software that serves their models private. Publishing it lets other engineers study and reuse parts of how DeepSeek serves its model. Ordinary users will not notice it directly.
What's next?
Watch for support for more DeepSeek models, the missing serving pieces, and outside tests of DeepSeek's benchmark charts.
Questions people ask
What is DeepInfer?
DeepSeek's inference framework, which it says powers its large-scale production services, now published as open source.
When was it released?
On 20 October 2026, on GitHub.
Which model does it support?
DeepSeek-V4.1-Flash, for now.
Which chips does it run on?
NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs.
Is it a full serving system?
No. DeepSeek says a KV cache system, prefill and decode disaggregation, and load balancing are not included.
Sources
Why "Confirmed"? We label a story "Confirmed" when the company or government announced it itself. Spotted an error? Email hello@openloopnews.com and we will correct it.